The problem
Every organisation has the same pile: decades of PDFs, scans and office files holding critical knowledge that no one can search, and that AI can't use — because it was never turned into structured, indexable content.
The File Parser solution
The File Parser example combines IntraLLM's document features into one ingestion pipeline:
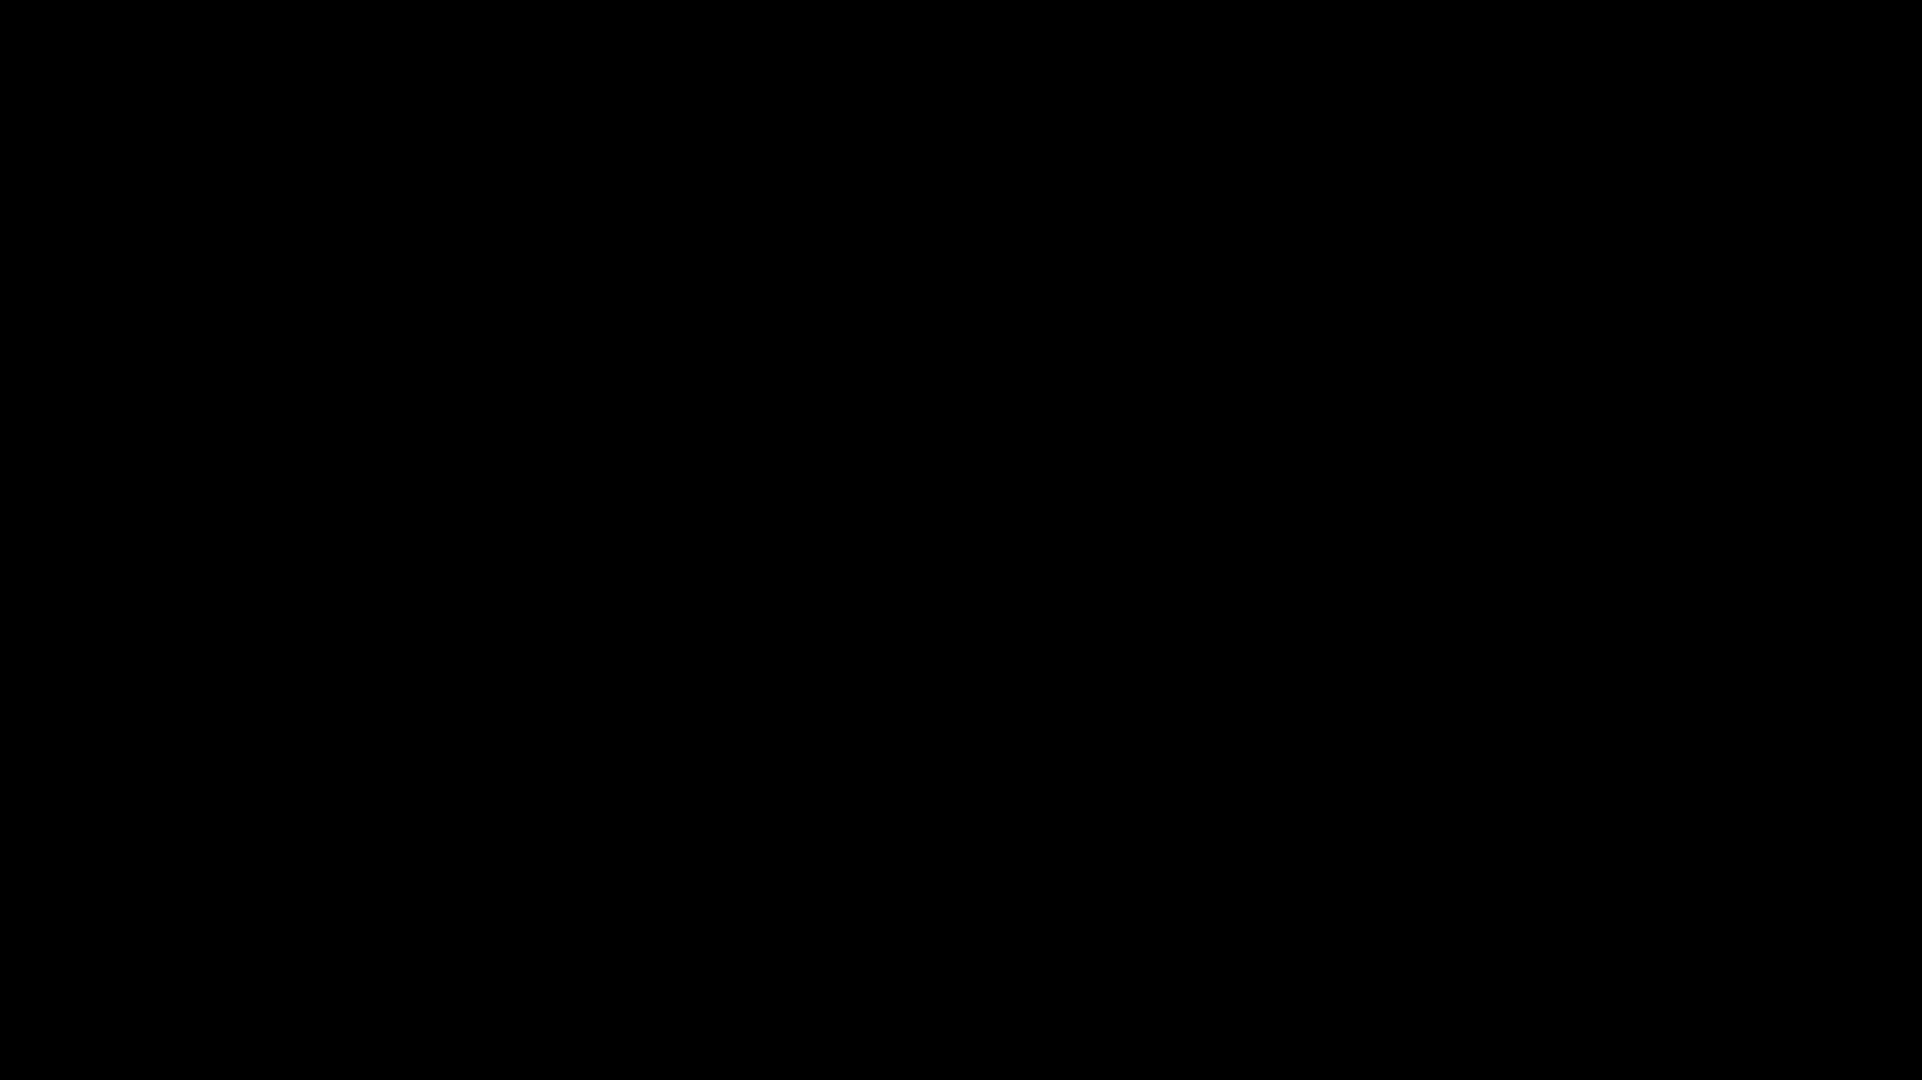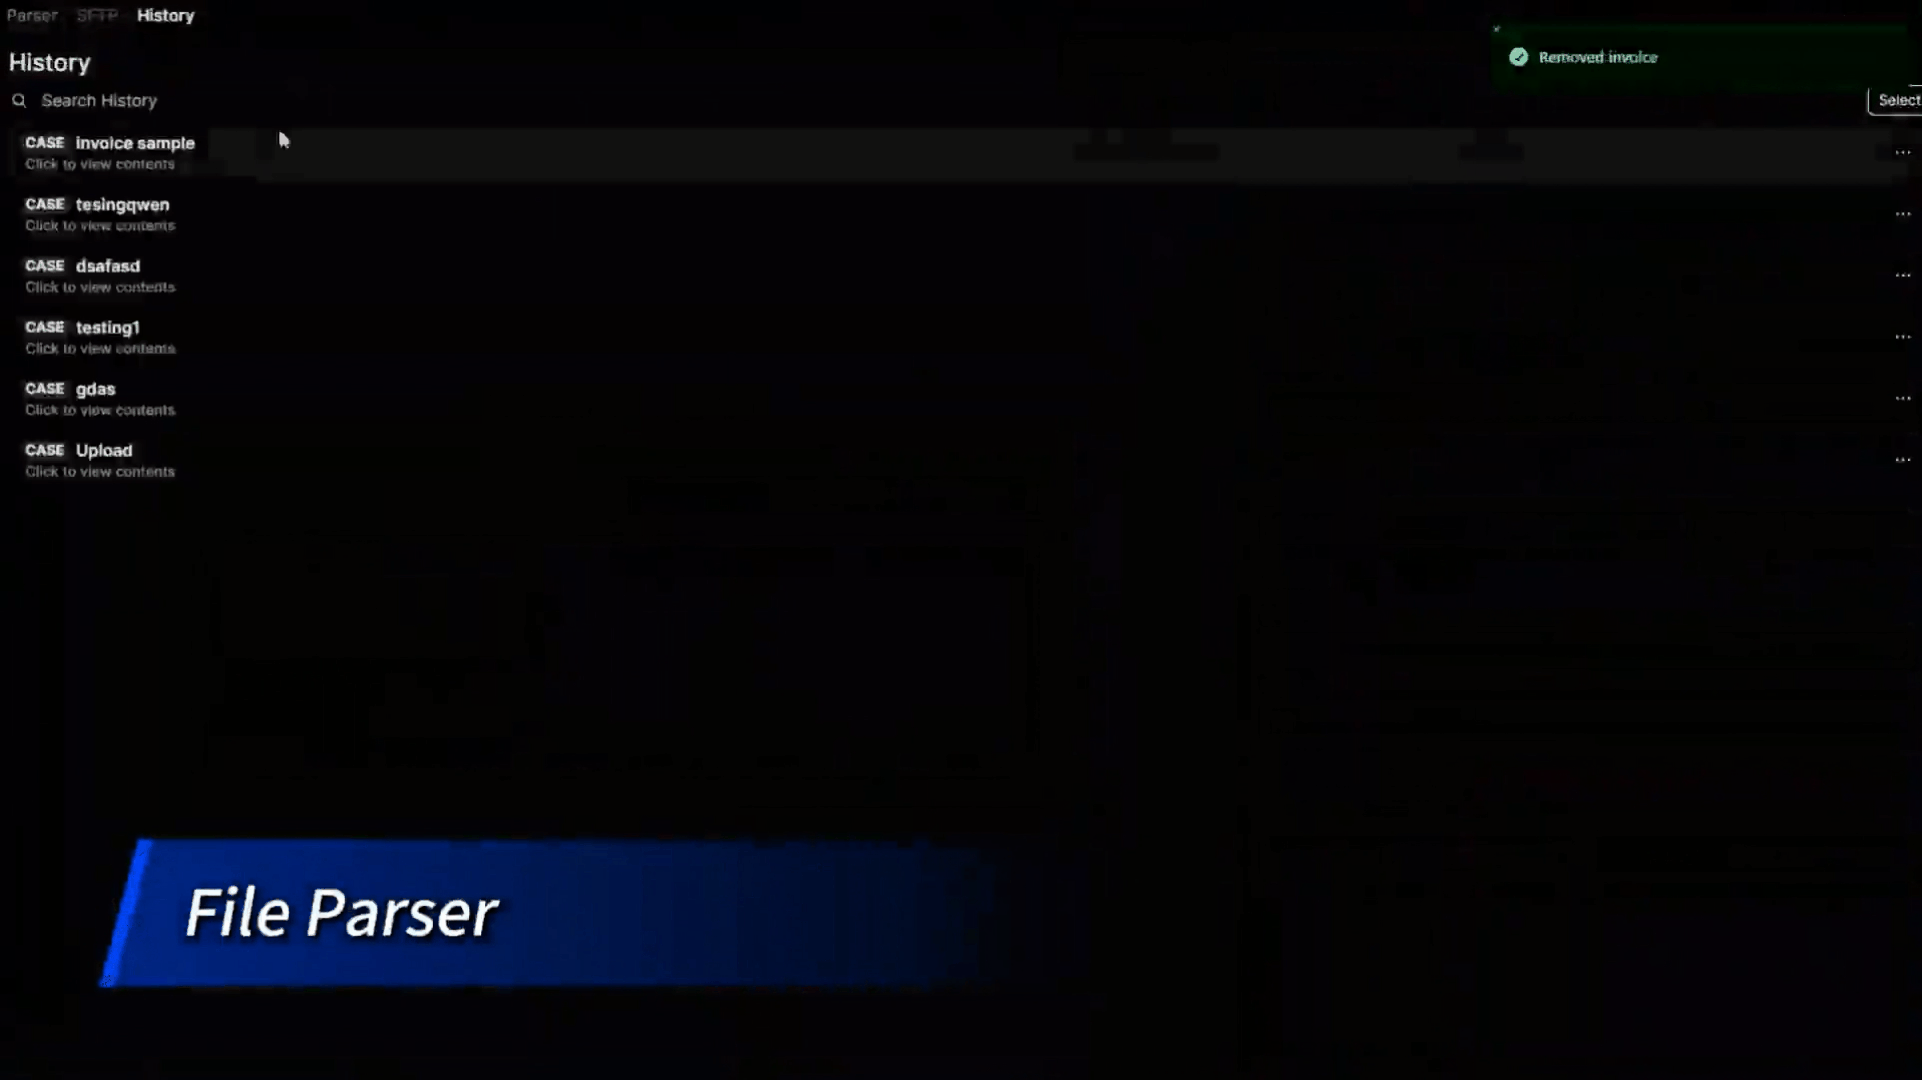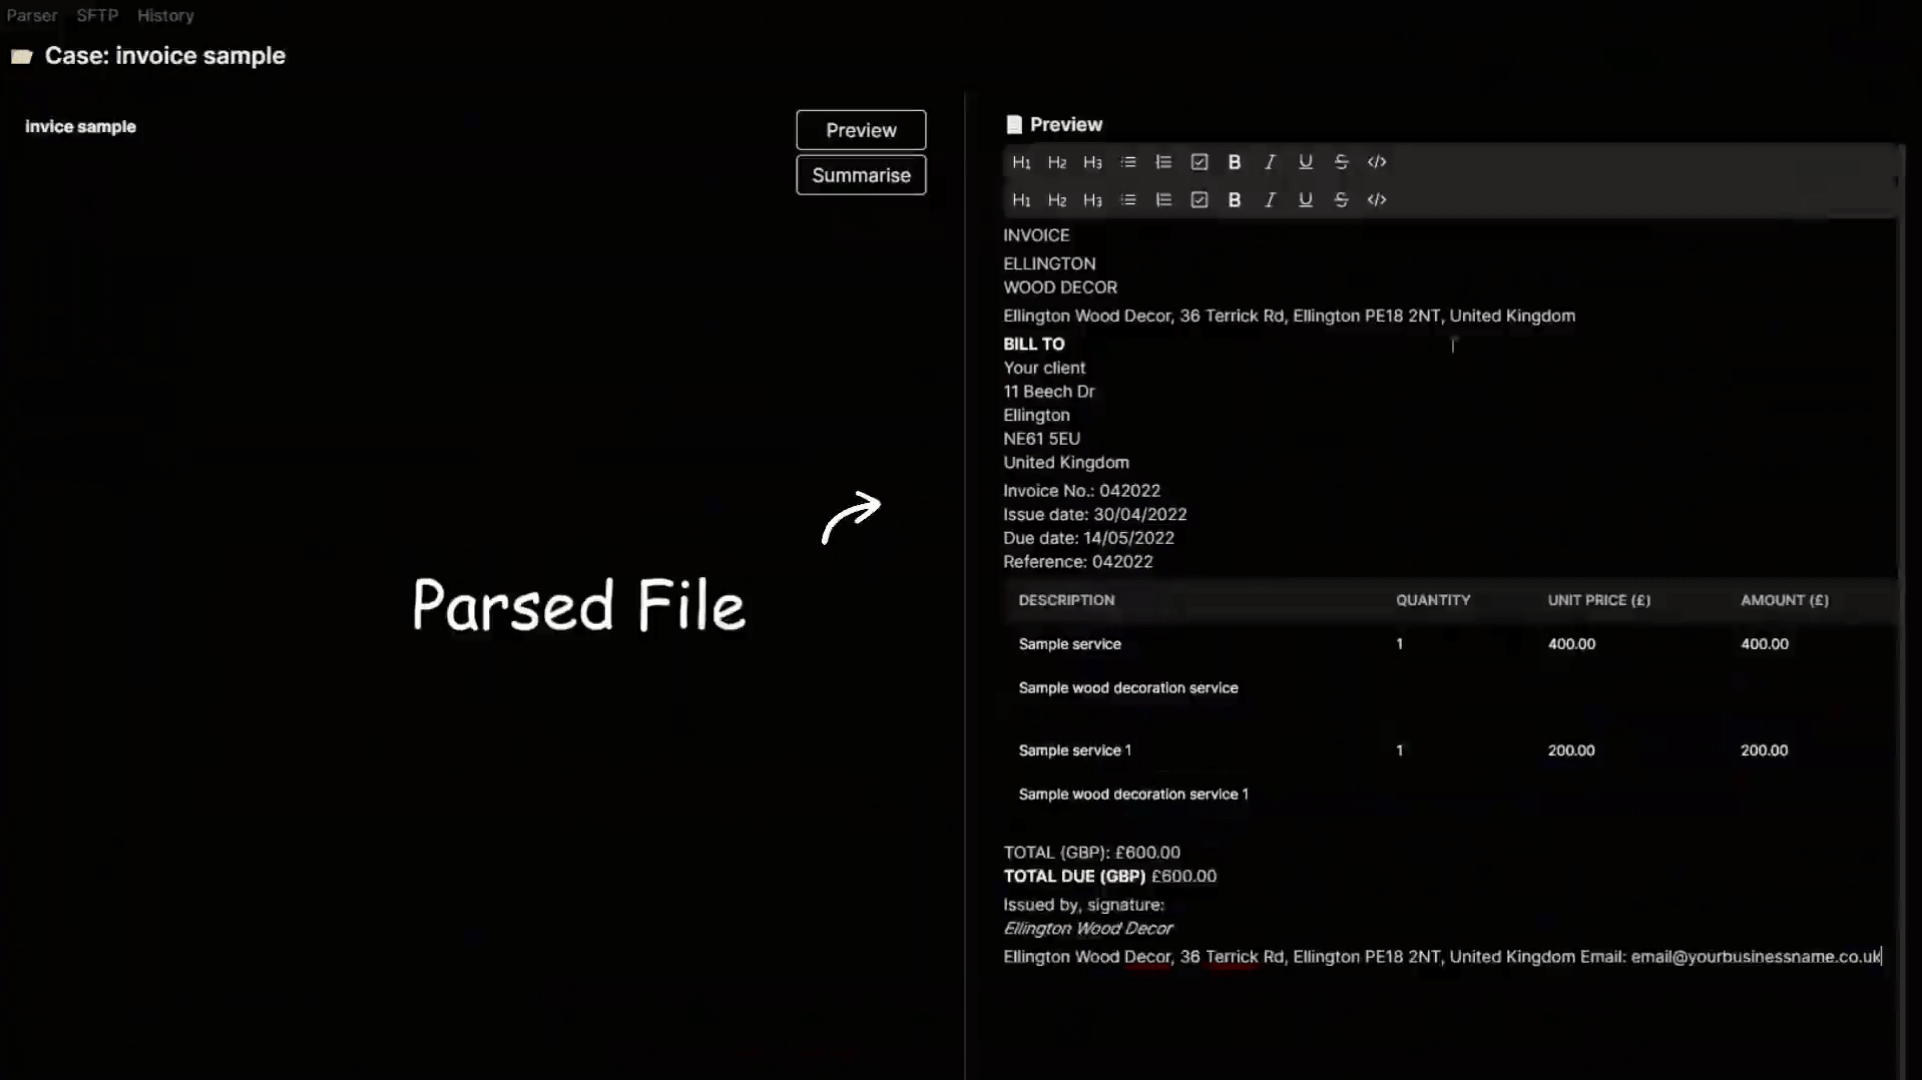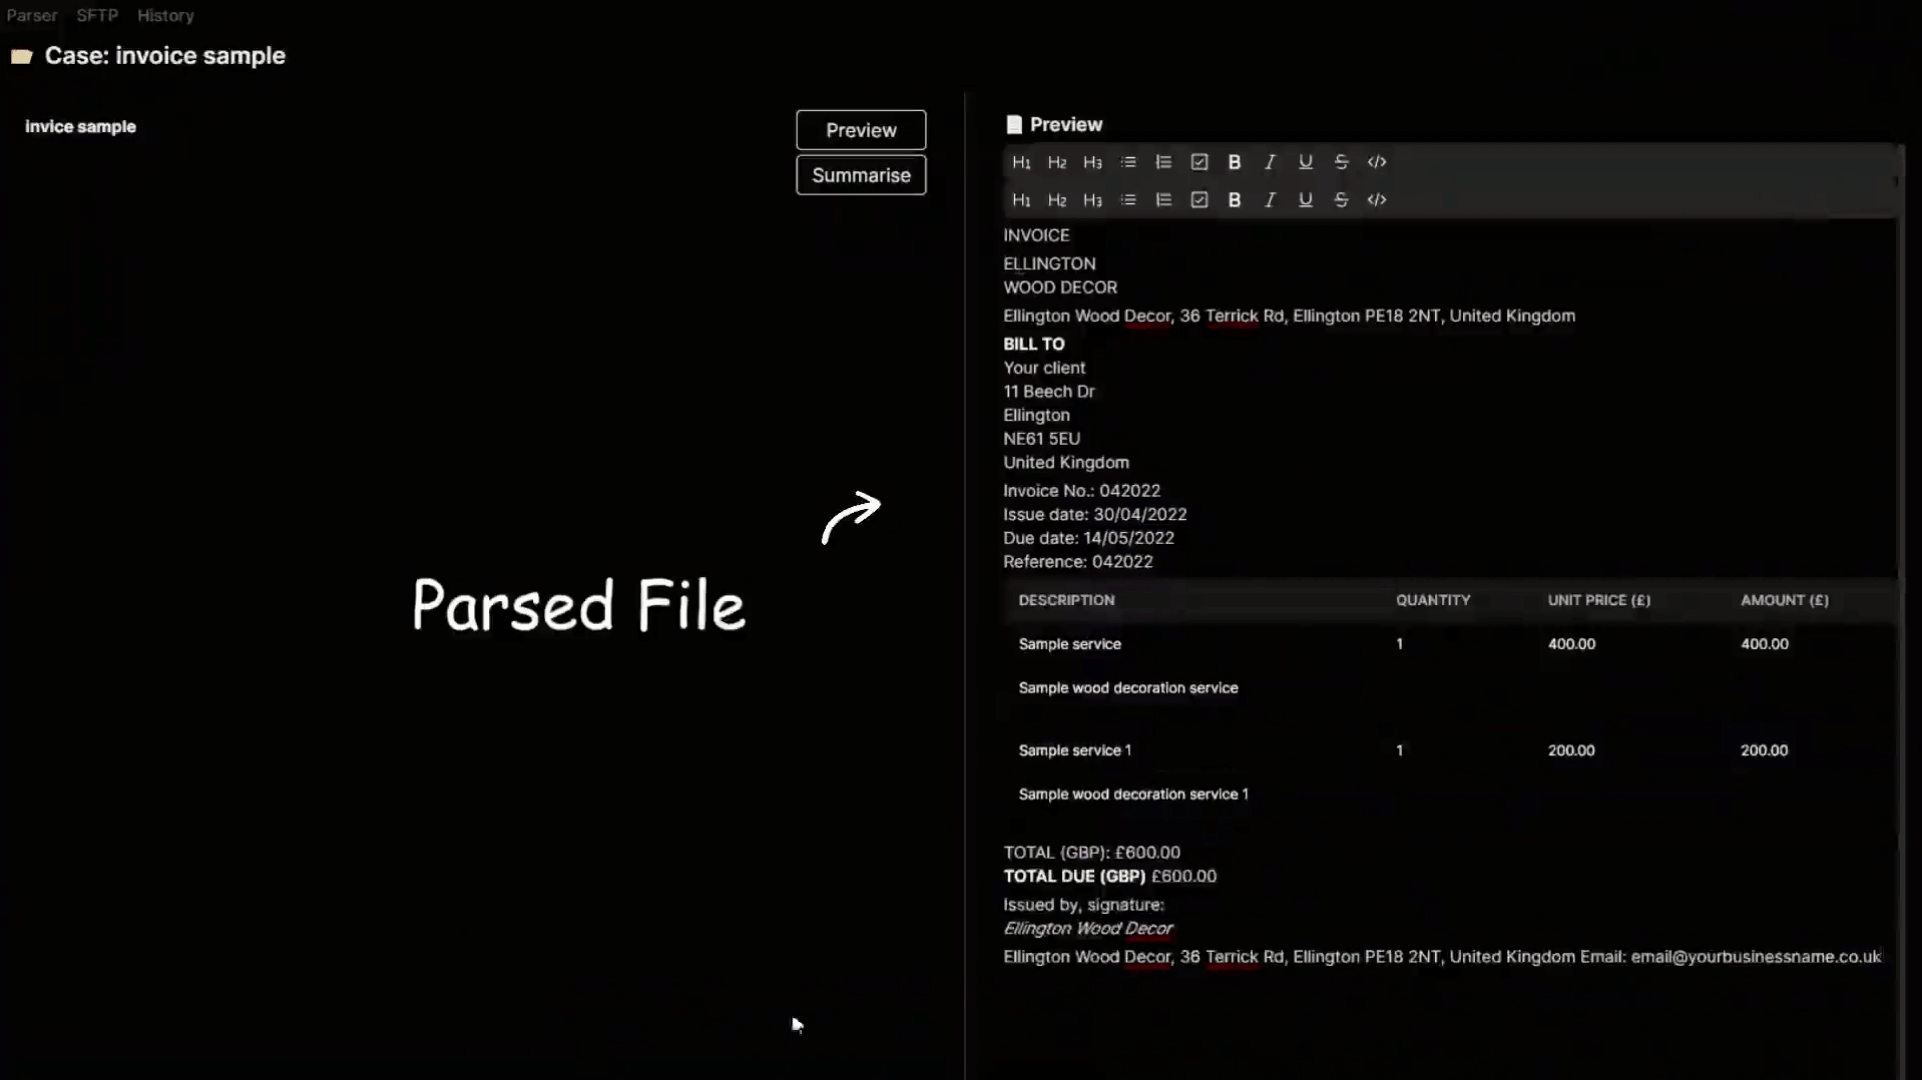
Upload folder → Parse (OCR + structure) → Classify → Extract fields → Knowledge base + structured exports
| Step | Feature used |
|---|---|
| Convert files to machine-readable text and tables | Document Parser |
| Sort by document type | Document Classification |
| Pull the fields you need | Data Extraction |
| Make it answerable in chat | Knowledge Bases & RAG |
| Automate the whole chain | Workflows |
Worked example: contract archive
- Ingest — upload the contract folder (hundreds of PDFs) to the parser.
- Classify — labels: NDA, MSA, SOW, Lease, Other.
- Extract — parties, effective date, expiry, renewal notice period, liability cap.
- Ground — load the parsed text into a
contractsknowledge base. - Use —
#contracts Which supplier agreements auto-renew within the next 90 days? - Export — the extracted fields become a CSV for the contract-management team.
Why it beats manual processing
| Manual | With the pipeline |
|---|---|
| Days of keying, error-prone | Minutes to hours, consistent |
| Knowledge in filing cabinets | Knowledge answerable in chat with sources |
| New documents need re-filing | Drop into folder, run pipeline |
| Audits take weeks | Query + export on demand |
Roll-out guidance
- Pilot with 50–100 representative documents; measure parse fidelity and extraction accuracy per field before scaling.
- Fix inputs where possible: original digital files parse better than re-scans. See quality tips.
- Put sensitive collections in group-restricted knowledge bases; automate the routine ones via workflows with approvals before export.